Hallucinations Across Domain Queries
Generic base models invent facts and misinterpret specialized business logic, producing inaccurate outputs that damage user trust and create operational risks.
Fine-tune foundational LLMs on your proprietary data with domain-specific adaptation, advanced RAG architectures, and custom guardrails. Eliminate hallucinations and deploy secure, high-accuracy AI models built for your business.
Our enterprise LLM customization platform is engineered specifically to eliminate hallucinations, enforce domain reasoning, and adapt foundation models to proprietary data.
Generic base models invent facts and misinterpret specialized business logic, producing inaccurate outputs that damage user trust and create operational risks.
Over-relying on generic commercial APIs with massive prompt stuffing skyrockets monthly inference bills, draining resources needed for product scaling.
Unstructured enterprise knowledge remains trapped in silos. Without automated embedding and curation pipelines, models cannot access internal ground truths.
Unoptimized model weights and missing quantization lead to sluggish response times, degrading real-time user experiences and interactive agent performance.
Sending confidential company data to third-party public models risks intellectual property theft and violates strict enterprise privacy and compliance policies.
Off-the-shelf models fail to maintain brand voice or follow complex multi-step reasoning guidelines without targeted DPO and parameter-efficient fine-tuning.
Without integrated guardrails and defensive filters, custom AI applications remain exposed to malicious prompt injections and unauthorized data extraction.
Without automated LLM-as-a-judge frameworks, engineering teams deploy prompt updates blindly, causing silent regressions and degraded output quality in production.
When vector stores, chunking logic, and embedding models are built haphazardly across departments, teams duplicate compute and produce contradictory answers.
Transform base foundation models into secure, domain-expert AI systems through an end-to-end customization pipeline. We combine automated dataset curation, parameter-efficient fine-tuning (PEFT), advanced RAG retrieval, and real-time guardrails to deliver enterprise-grade accuracy, low latency, and zero hallucination.
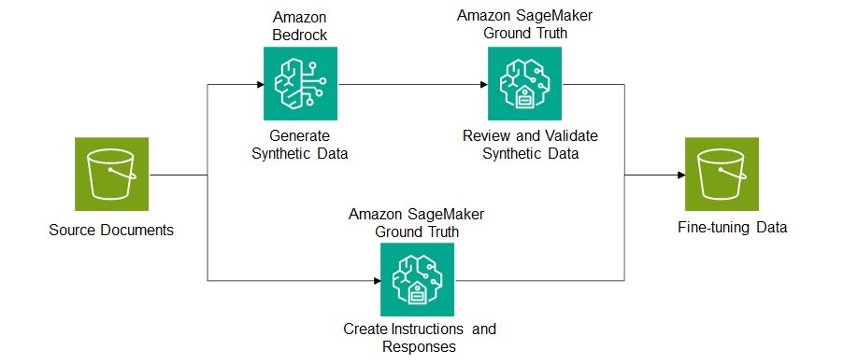
Ingest enterprise documents, codebases, APIs, and customer conversations into structured instruction-tuning datasets with automated deduplication, PII redaction, and semantic chunking.
Generate high-diversity synthetic QA pairs, reasoning traces, and multi-turn dialogues while enforcing strict data validation to eliminate bias, noise, and low-quality training samples.
Select the optimal open-source or proprietary base model (Llama, Mistral, Qwen, Claude) based on your context window demands, latency budgets, licensing terms, and hosting needs.
Adapt model weights to your specialized industry taxonomy using low-rank adaptation (LoRA/QLoRA) and full parameter tuning, minimizing GPU memory footprints and training costs.
Align customized model behaviors to corporate tone, security policies, and domain logic using Direct Preference Optimization (DPO) and Reinforcement Learning from Human Feedback.
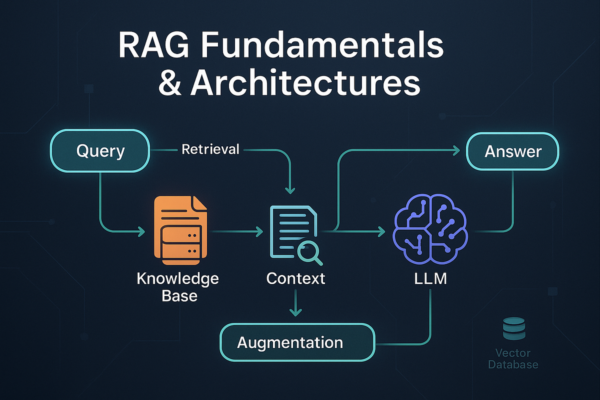
Ground model responses in real-time knowledge graphs, dense vector indexes, and hybrid BM25 search systems to provide citation-backed, verifiable answers without hallucination.
Evaluate customized model accuracy, instruction following, and reasoning quality using automated LLM-as-a-judge pipelines, golden test suites, and RAG triad metrics.
Maximize inference throughput and reduce GPU costs using model quantization (AWQ/GPTQ), continuous batching with vLLM, and intelligent context caching architectures.
Protect live endpoints with real-time prompt injection defense, output content moderation, and active learning loops that capture edge cases for iterative model fine-tuning.
Discover the foundational tools and advanced infrastructure powering our LLM customization platform, engineered to fine-tune proprietary models, accelerate domain alignment, and scale private AI deployment.
Our LLM customization platform connects your entire generative AI lifecycle, from raw data preparation and parameter-efficient fine-tuning to RAG alignment, guardrails, and secure private hosting.
Clean, tokenize, deduplicate, and convert enterprise data into structured instruction-tuning pairs. Generate high-quality synthetic datasets with strict privacy and quality controls.
Adapt open-source foundation models to domain-specific terminology and structured outputs using LoRA, QLoRA, and full parameter tuning while minimizing compute overhead.
Connect models to enterprise knowledge repositories using hybrid vector indexing and semantic retrieval. Deliver citation-backed, verifiable answers with zero hallucinations.
Track token usage, prompt-response latencies, drift metrics, and retrieval accuracy in real time. Gain instant operational visibility into live AI agent performance.
Quantize weights via AWQ and GPTQ, enable continuous batching with vLLM, and optimize token throughput to drastically lower cloud infrastructure and serving costs.
Benchmark model variants with automated LLM-as-a-judge pipelines, golden test suites, and RAG triad metrics to prevent regressions prior to production rollout.
Enforce real-time prompt injection defense, automated PII masking, toxic content filtration, and corporate governance rules across every inbound and outbound request.
Deploy fine-tuned model endpoints within dedicated Virtual Private Clouds (VPC) or on-premise GPU clusters for absolute data sovereignty and air-gapped security.
Monitor model quality metrics, task completion rates, inference spend, and domain accuracy across business units from a single centralized executive dashboard.
Tailor foundational large language models to your proprietary data with domain-specific fine-tuning, advanced RAG architectures, and enterprise guardrails.
Build modular, cloud-native applications engineered around your exact business logic, ensuring effortless scalability as your operations and user demands grow.
Unify your digital ecosystem by connecting legacy infrastructure, third-party services, and microservices through secure, high-throughput APIs.
Clean, tokenize, and augment enterprise datasets with automated pipeline validation to ensure high-quality training pairs and zero data leakage.
Benchmark customized models against industry standards with automated LLM-as-a-judge frameworks, latency profiling, and semantic scoring.
Implement real-time prompt defense, PII masking, and output safety guardrails to enforce strict corporate compliance and regulatory governance.
Deploy quantized models on dedicated VPCs or on-prem clusters with vLLM acceleration, cutting token latency and compute infrastructure costs.
Data curation, parameter-efficient fine-tuning, and RAG architectures converge seamlessly—slashing token latency, eliminating hallucinations, and scaling domain-specific AI with verifiable enterprise compliance.
Define Enterprise Use Cases
Audit
& Curate Training Data
Configure LoRA
& RAG Architecture
Fine-Tune
& Embed Vector Pipelines
Deploy Endpoints
& Enforce Guardrails
Benchmark Accuracy
& Token Latency
GCTL LLM Customization Platform combines automated dataset curation with parameter-efficient fine-tuning (PEFT) and hybrid RAG to adapt foundation models to your proprietary data, eliminate hallucinations, and accelerate enterprise AI deployment.
Smart algorithms adapt model weights to domain-specific terminology and structured schemas using low-rank adapters, eliminating hallucinations while minimizing compute costs.
Live engineering dashboards track token latency, instruction drift, benchmark scores, and endpoint GPU utilization without fragmented monitoring scripts.
Centralize enterprise knowledge bases, vector embeddings, and custom adapter checkpoints in a secure VPC ecosystem, providing development teams instant access anywhere.
Instantly convert unstructured enterprise documents and API schemas into verified instruction-tuning pairs, eliminating data engineering bottlenecks.
Seamless integration with enterprise vector stores automatically grounds model responses in live company data and delivers citation-backed outputs.
Streamline model governance with direct preference optimization, customized safety scoring, automated LLM-as-a-judge suites, and instant regression reports.
Built-in security layers enforce real-time PII masking, toxic content filtration, jailbreak protection, and compliance policies directly at inference endpoints.
Empower developers and field agents to run lightweight, quantized LLMs (AWQ/GGUF) on resource-constrained devices and mobile apps with ultra-low latency.
Evaluate deployment efficiency with comprehensive reporting on token consumption, GPU cluster utilization, API costs, and departmental model usage.
Chief Technology Officer / Fintech Founder
Partnering with their custom software development team completely revamped our core transaction engine. Migrating away from rigid off-the-shelf tools to a high-throughput microservices architecture was flawless. Our automated API pipelines now process millions in daily volume with zero latency.
VP of Product / Enterprise SaaS Director
Their agile engineering expertise and technical discovery process gave us complete clarity from sprint zero. The custom multi-tenant architecture and CI/CD pipelines they implemented cut our feature release cycles in half. Their dedicated engineering team sets the gold standard for full-stack delivery.
Head of Digital Transformation / HealthTech CEO
The custom platform they engineered exceeded every strict regulatory and compliance benchmark we needed, including HIPAA and SOC 2. They modernized our legacy databases into an intuitive, secure cloud system that our operations team adopted effortlessly on day one.
Chief Operating Officer / Logistics Enterprise
We needed a tailor-made ERP solution to unify global supply chain tracking, automated invoicing, and real-time fleet analytics under one roof. Their custom software solution delivered precisely that, saving us thousands in recurring licensing overhead while scaling our operations seamlessly.
Enterprise-Grade Large Language Model Customization Platform For Domain Fine-Tuning, Advanced RAG, and Real-Time Safety Guardrails
It is an end-to-end framework that adapts foundational AI models to your proprietary business data and domain workflows using parameter-efficient fine-tuning (PEFT), instruction alignment, and retrieval-augmented generation (RAG) instead of relying on generic public APIs.
We typically complete data curation, adapter training (LoRA/QLoRA), benchmark evaluation, and private cloud deployment within 15 to 25 days. Our engineering team handles data preprocessing, quantization, and endpoint integration directly to ensure rapid production readiness.
It embeds your industry terminology, internal style guides, and proprietary logic directly into the model's weights. Combined with real-time vector search, it eliminates generic hallucinations, ensures citation-backed answers, and dramatically reduces prompt-engineering overhead.
Essential capabilities include automated dataset cleaning, multi-turn synthetic data generation, parameter-efficient LoRA/QLoRA fine-tuning, automated LLM-as-a-judge benchmarking, model quantization (AWQ/GPTQ), and enterprise-grade PII filtering guardrails.
It lowers recurring token and API costs by optimizing smaller, domain-specific models, protects proprietary corporate intellectual property within your private cloud, and accelerates task automate.